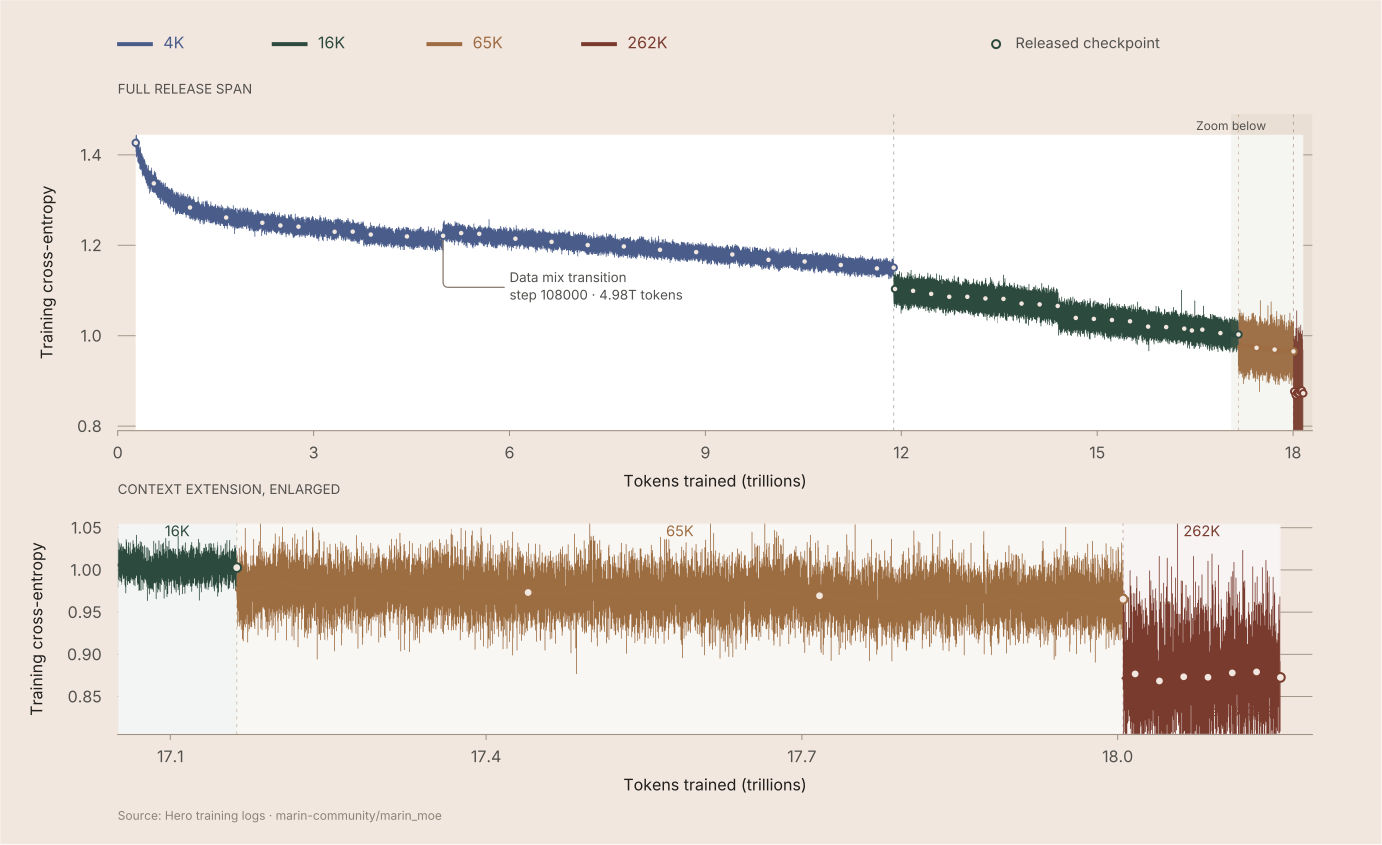
We’re pleased to announce that Marin “Mochi” 535B-A23B has finished its main phase of pre-training. We’re still running evals and figuring out post-training, but we’re ready to share all the checkpoints we have so far.
We also have separate blog posts with more information about our pre-training process, training data curation, and our architecture. All the details can be found in our GitHub issues (#8435, #8506) and Wandb report. We’ll have much more to say in the coming days and weeks, including a proper tech report.
The pre-training checkpoints are uploaded on Hugging Face: huggingface.co/open-athena/Marin-Mochi-535B-A23B. There are 57 checkpoints total, 10 of which are from the long context extension phase.
A note on evaluations: During training, unexpected changes in evaluation loss, together with concerns raised by Stanford student Michael Ryan, led us to investigate benchmark contamination more closely. We discovered substantial leakage from common pre-training benchmarks that our decontamination procedure had missed. This affects which evaluations we can fairly report to compare Mochi against other models.
Releasing pre-training artifacts of large models naturally raises safety concerns. These concerns must be weighed against academia's and the public's interest in studying how large models are trained. We believe that open development also contributes to safety by enabling independent researchers to scrutinize how powerful models are built. In particular, safety researchers at independent organizations have only very limited access (if any) to pre-training artifacts from the closed frontier labs, which severely limits their ability to do valuable research.
While our models are not yet at the capability frontier, we're increasingly getting requests to study our work as a proxy for what happens inside the closed frontier labs. We view this release as a way of supporting that work.
It's also worth distinguishing these checkpoints from the finished models available from frontier labs. At the closed frontier, post-training now consumes enormous amounts of compute, often far exceeding pre-training itself. Much of the most concerning agentic behavior of today's frontier models can be traced to their extensive post-training. In particular, reinforcement learning has substantially improved their ability to pursue goals, use tools, and complete long-horizon tasks. Achieving these capabilities has required enormous additional investment in compute, data, and engineering. Our intermediate pre-training checkpoints have undergone none of this post-training.
We therefore believe that the benefits of making these pre-training checkpoints available to researchers outweigh the risks of their release. Finally, these are intermediate pre-training checkpoints without any instruction tuning. They have not undergone safety post-training and should not be treated as ready-to-deploy assistants. They are intended for scientific study or as a basis for further training.
Looking forward, we highly value making as much of our work public as possible, both the process and the artifacts. With artifacts, there may be times when it's not practical or possible to share everything: we might lack the bandwidth or storage to do so, we could have legal or safety concerns, and so on. We'll always do our best to be transparent about what we aren’t sharing and why.
As we move into post-training, we'll continue to consider the benefits and risks of releasing each artifact, recognizing that the balance may change as capabilities evolve. We won't release an artifact if we conclude that the risks outweigh the benefits, and we'll do our best to explain our reasoning publicly.
We’re excited that this phase of training is done, and we’re poring over the results, working towards more blog posts and a technical report. As always, please join us on our GitHub and Discord. We’d love to hear what you discover.
Cite this post
@misc{hall2026_marin_mochi_pretraining_checkpoints,
  author = {Hall, David},
  title = {Initial Pre-Training Checkpoints for Marin “Mochi” 535B-A23B},
  year = {2026},
  month = {nov},
  howpublished = {\url{https://www.openathena.ai/blog/marin-mochi-pretraining-checkpoints/}},
  note = {Open Athena Blog}
}